Featured Project
ScrollSeeker V2
An ancient manuscript processing pipeline built to bring old worlds into clear focus — combining OCR, image preprocessing, and machine-learning classification to read, translate, and organize historical documents at scale.
What It Does
ScrollSeeker V2 takes scanned or photographed historical documents and runs them through a full processing pipeline — cleaning up image quality, extracting text with OCR, classifying document type and era, and translating content for modern readers. It’s built to handle the noisy, degraded, and handwritten sources that trip up most off-the-shelf tools, turning fragile archives into searchable, structured data.
See It In Action
A look at the ScrollSeeker V2 interface
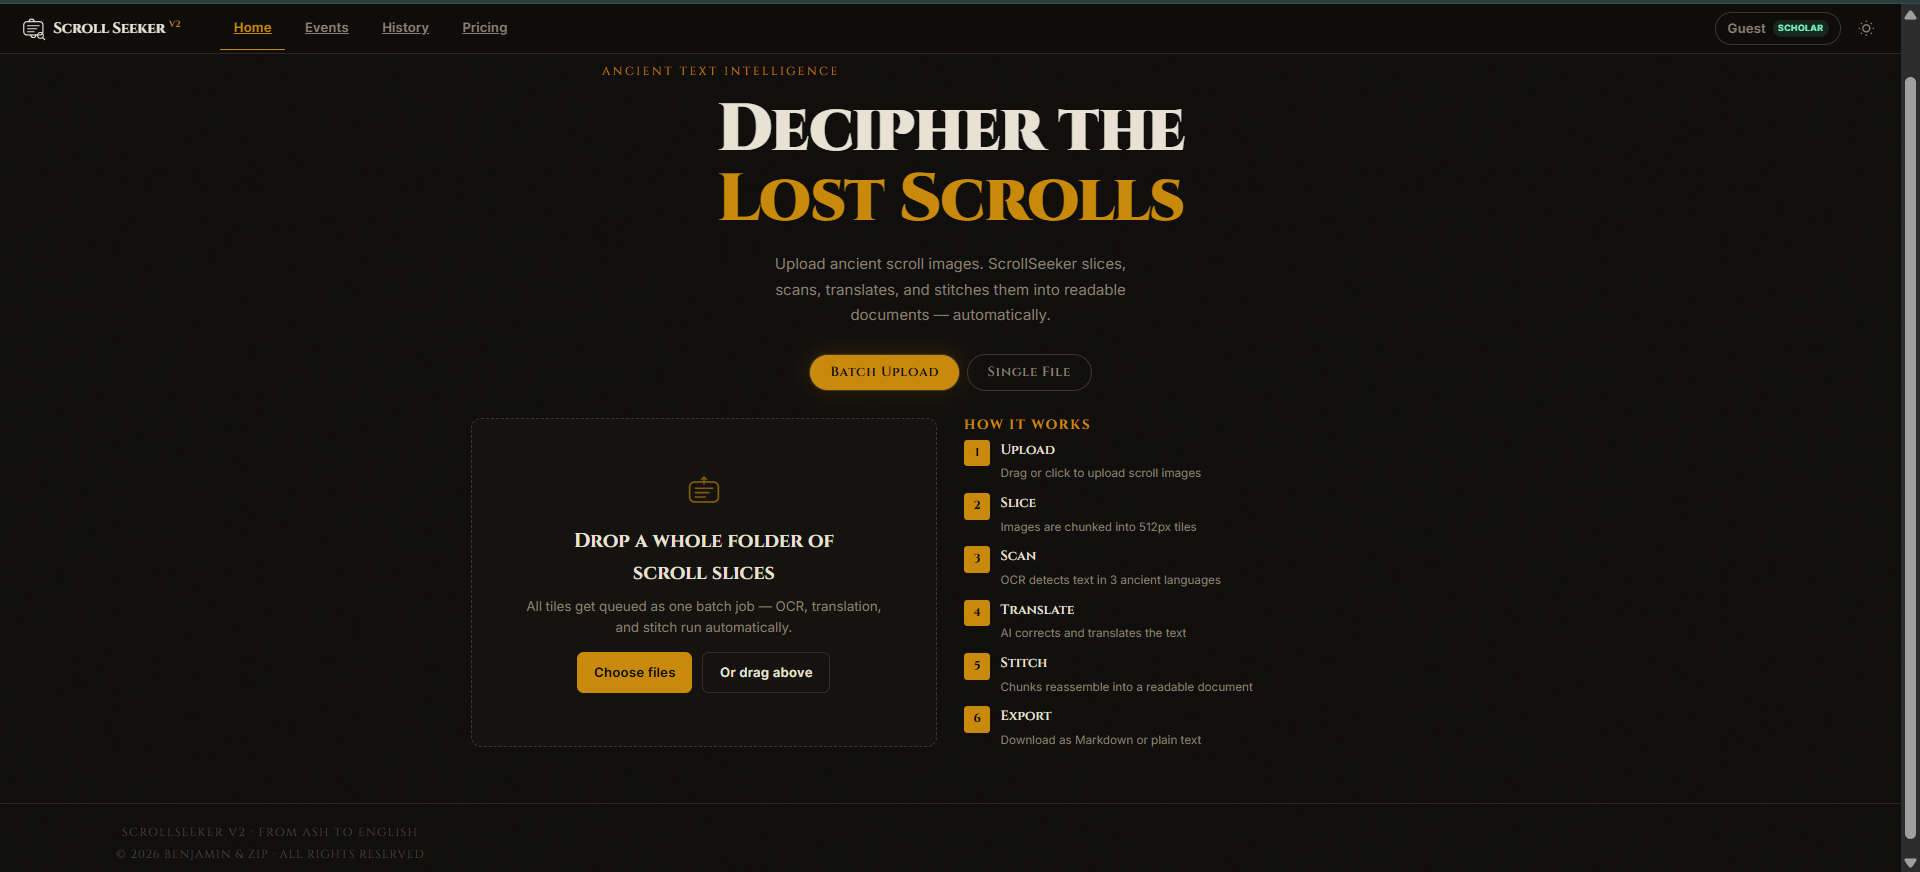
Upload & Scan
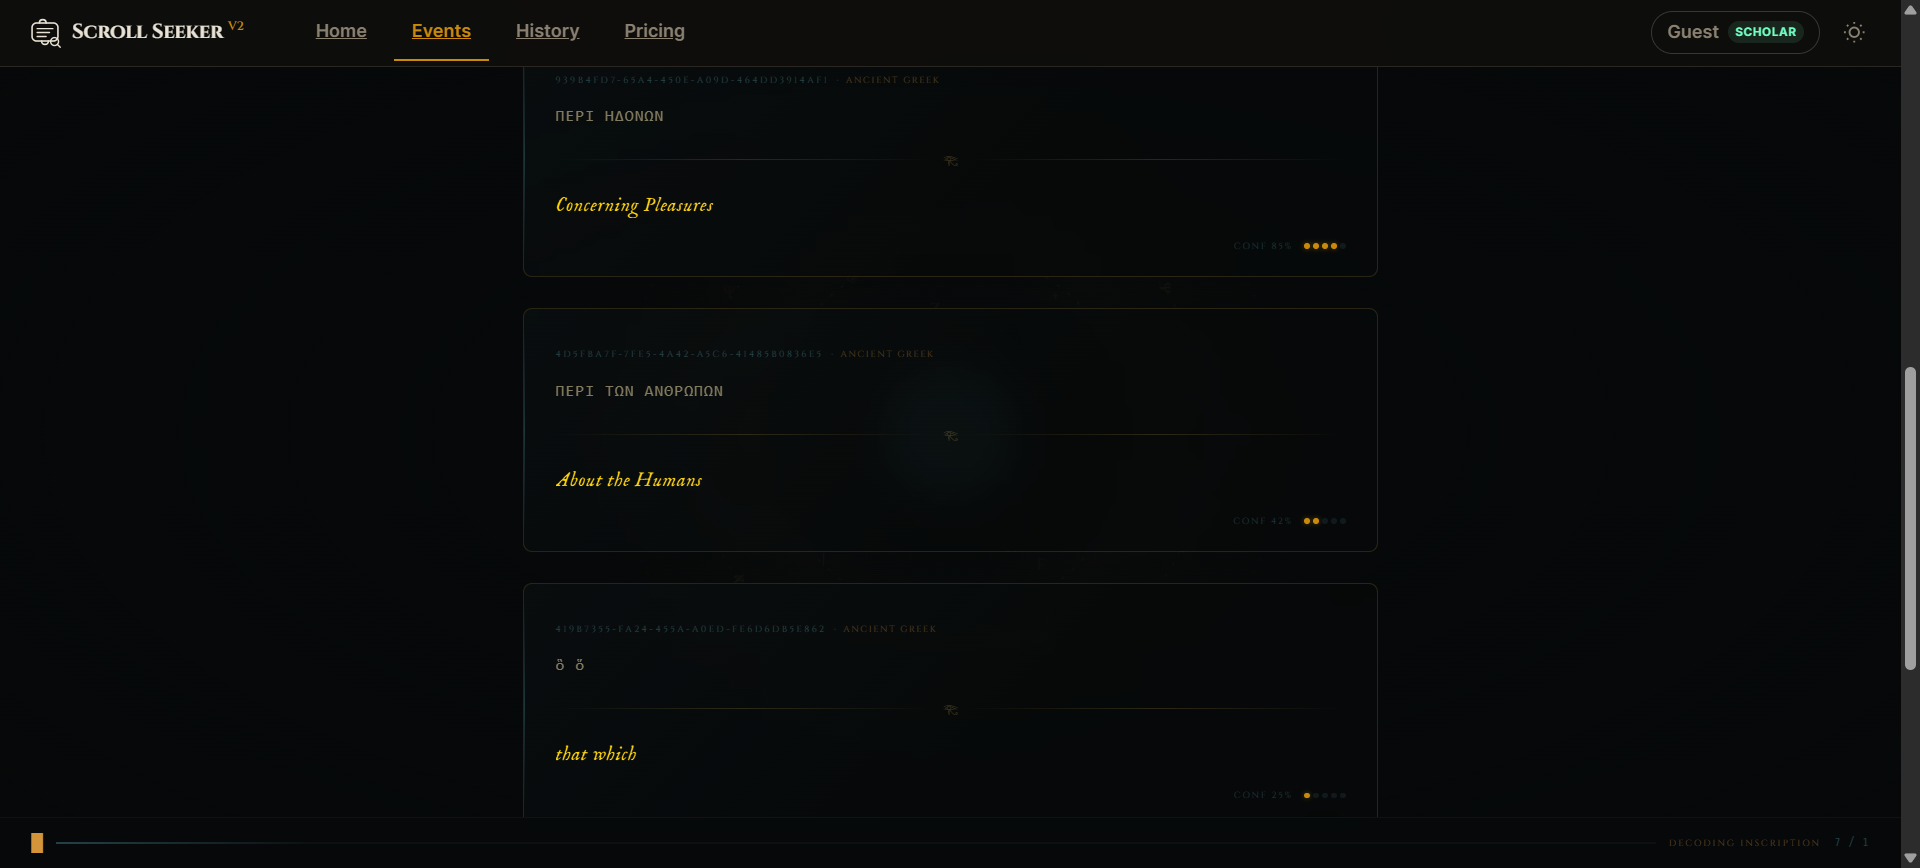
Translated output
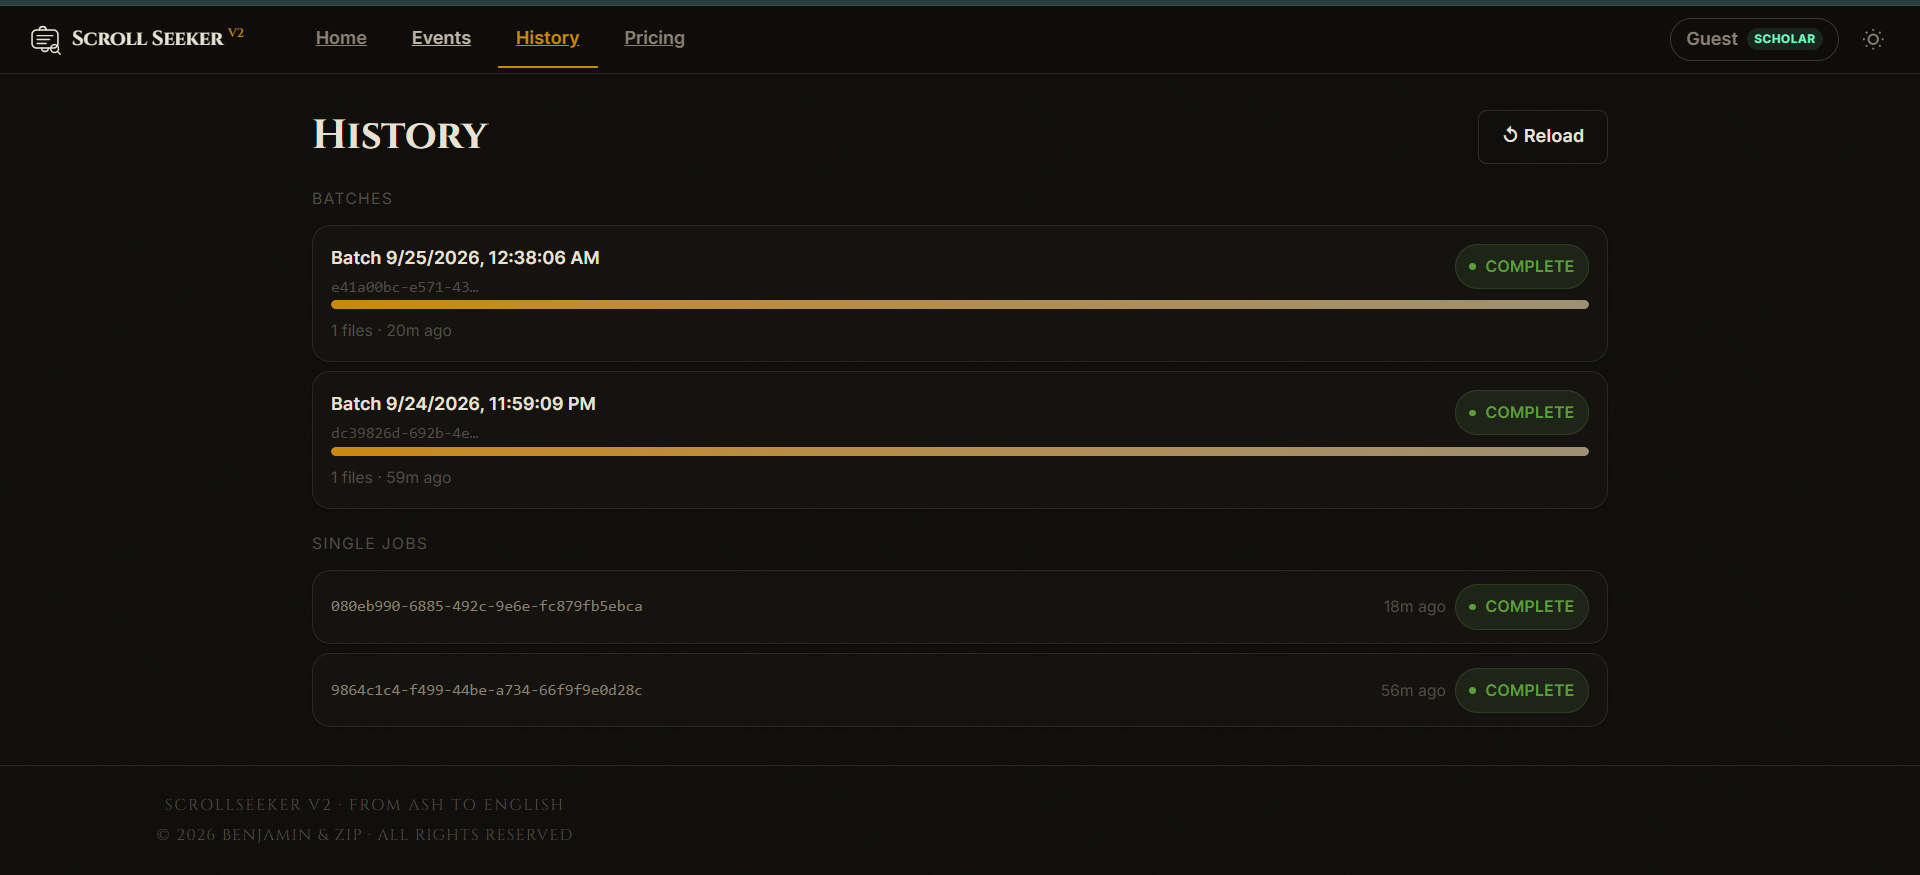
STICHER
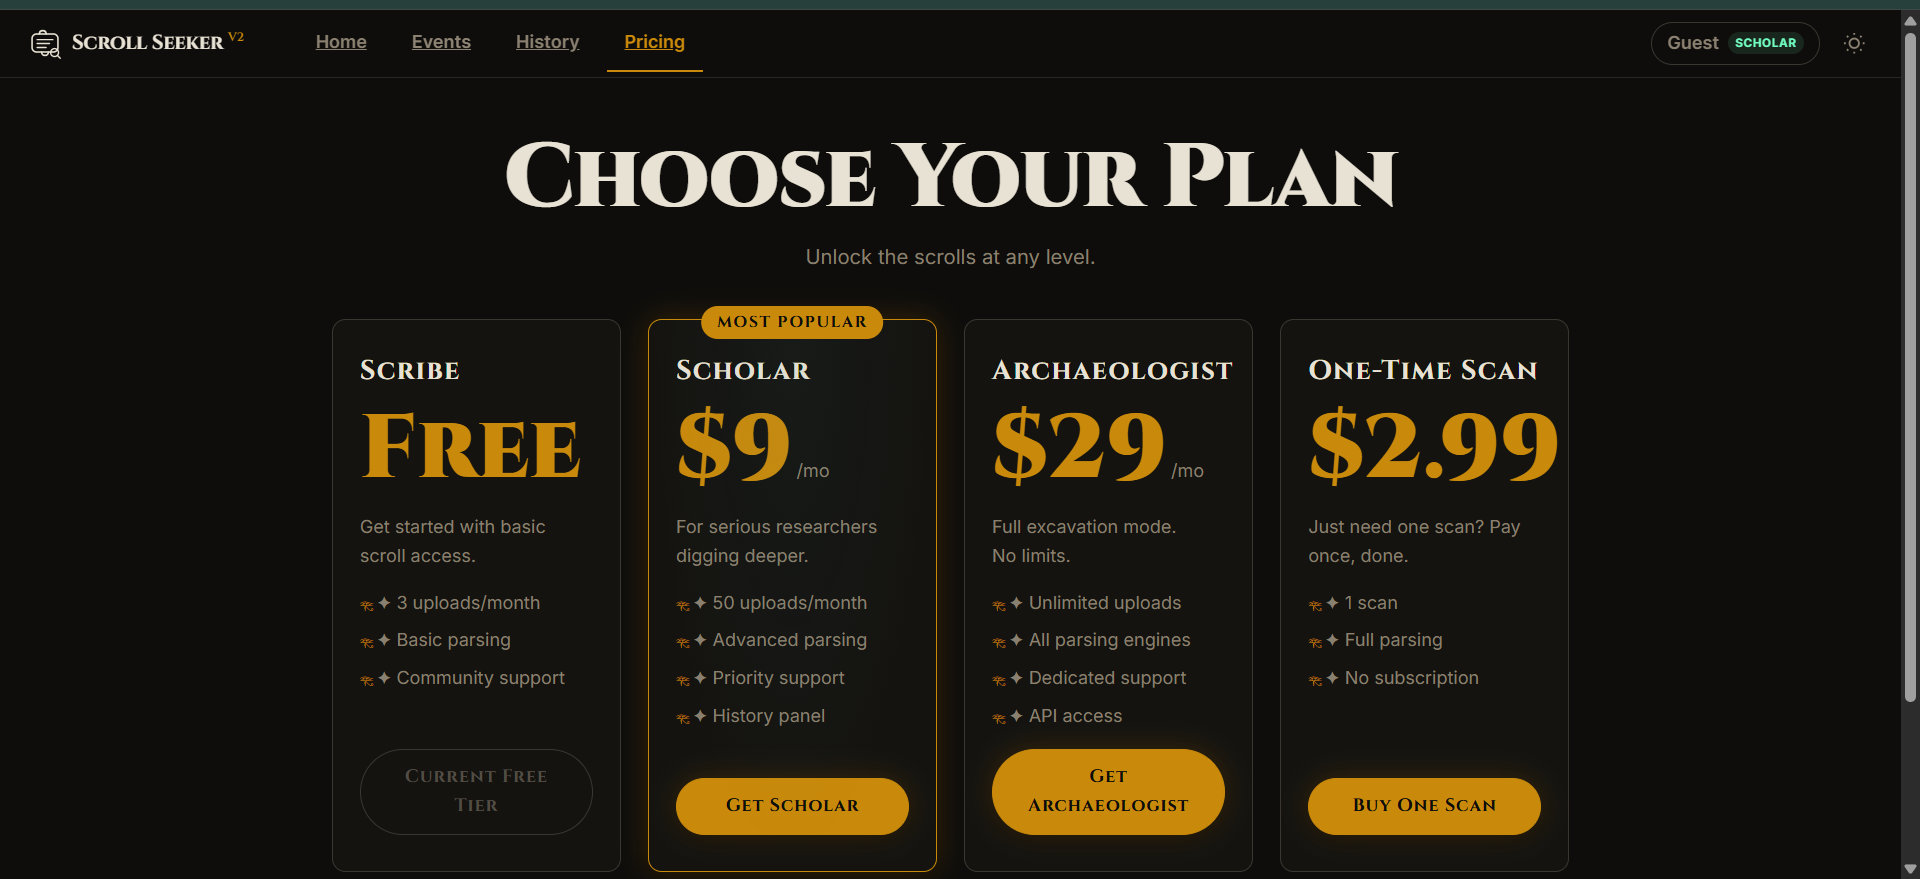
Pricing